Showing posts with label Tutorial. Show all posts

Saturday, May 31, 2014

End to End Example - A Mule 3.5.0 App with Domains

Recently, I've added to my gradle plugin for building mule apps the ability to build domain-based (A.K.A. mule shared resources) projects. While the plugin gains maturity and is getting ready for prime time, I've started eating my own dog food with it and as a result I've produced a sample application that uses some features of Mule 3.5.0 Community Edition. Please checkout the instructions on how to run the sample project.

The Use Case

Let's imagine that we have in our premises a database of cooking recipes, but we have the requirement of exposing a REST API so users can check available recipes and post new ones.

This is a simple use case but we have some additional requirements as well as some constraints:

  1. The Backend APP needs to have the less down time possible.
  2. We need to be able to change the API since it will evolve and gain new features.
  3. We need to be able to scale the backend so when thousands of users access it at the same time it does not become extremely unresponsive.
  4. Upon an upgrade in the backend it would be desirable that users can still post recipes. 

Implementation

For the implementation of these requirements, I've decided to divide and conquer, this is create two modules:
  1. API Module: This is responsible for receiving requests through HTTP, and adapt them in a way the backend can understand and process them. Also is responsible for representing appropriately the information provided by the back-end.
  2. Backend Module: This module is responsible for accepting requests, processing them and returning the results.
The following is a diagram of the implemented architecture:
The communication between the modules is leveraged through JMS, initially as the app has only a couple of users, we don't want to have a separate JMS Broker, so we'll leverage an embedded broker, but this is easily upgradable to an external broker without making any changes to the Modules.

Backend Implementation

For implementing the backend (source code) I've leveraged the brand new Database Module. This module allows to easily run parameterized queries. The backend module's main interface are JMS queues, and for the operations that require a response, we'll take advantage of mule's automatic reply when ReplyTo-type headers are present.

API Implementation

For implementing the front end (source code), I've used APIKit, this module allows us to easily expose a REST-like API out of a RAML file, so before starting the implementation I went to the Anypoint Platform website and created a RAML File with the API Editor.

In order to implement the requirement of accepting recipes even if the backend is missing I used a Asynchronous approach, this is the create operation returns a Task ID, and it's up to the client to check if the task has been completed, normally it is desirable that the APP itself notifies the clients when their tasks have been completed, nevertheless due to the nature of the HTTP transport, this is not possible.

There are some tasks that require a synchronous response, these are: check the list of recipes and check the status of a given task. These calls have been implemented with JMS queues as well, but leveraged mule's request-reply router for synchronizing these calls, so if a redeployment of the backend happens in a reasonable time-frame, requests from the client will last a little longer but not fail.

Conclusions

The use of Mule ESB 3.5.0 allowed me to implement this use case in a matter of a couple of hours. In particular this version with the ability of sharing the JMS connector I can easily do Inter-APP communication (which is easier in Mule Enterprise by sharing a VM connector) and still have the ability to scale, add more servers, cluster etc.

Wednesday, February 26, 2014

Building Mule Applications with Gradle

Some time ago I discussed the advantages of building applications with gradle against maven or other build systems. I have been working since on a gradle plugin that enables Mule ESB users to build their apps with gradle as an alternative to maven.

While I continue to add features to this plugin, it is currently stable enough to build any community-based mule project and the plugin is open source based on the Apache 2 license. The url for the plugin and install instructions is the following:

https://github.com/mulesoft/mule-gradle-plugin

The project aims to cover all the features the current Mule plugin for maven does and some other use cases that might be difficult for the maven plugin to achieve. The plugin is oriented for both community and enterprise users of Mule ESB.

Using the Plugin With MuleStudio

In order to enable an existing MuleStudio project, you need to follow the following steps:
  1. Install the gradle plugin into your plugin repositories. The README file suggest how to install it and use it in your local maven repo.
  2. Create a MuleStudio project or choose the one you'd need to enable with gradle.
  3. Add a build.gradle file in the root of your project with the following contents:
This base build script may be customized to include any dependencies your project may have but bare in mind that most of the libraries included in the Mule ESB runtime are already there in the 'provided' scope.

To upgrade your MuleStudio classpath automatically, you just need to run:


$ gradle studio

You need to run the previous command every time you update dependencies in your project. The mule version needs to match the version of the runtime you're using.

To build your app so it is deployable in a standalone studio, you just need to run:


$ gradle mulezip

This will place the deployable zip file in the build directory. The plugin is as well capable of running the app in an embedded mule instance or installing it into a Mule ESB instance installed on the same host.

Tuesday, December 31, 2013

Migration of a Maven-based project to Gradle


Recently I've started noticing that some of the big names in java open source have migrated their builds from Maven to Gradle.

To my own development needs, Maven was good enough, so for some time I remained sceptic with Gradle and carried on working with the former. Today I gave Gradle an opportunity and so far I find it has been amazing.

As with any new technology, to gain adoption you can't just simply be "better" because for most of the people, changing stuff require a lot of effort, so marginal improvements are simply not strong enough, you need to be radically better. I believe the creators of Gradle had this in mind when they created this tool.

The learning Curve

Any tool has it's own learning curve so, before I even tried to do something with it, I started reading the documentation. At the very beginning, it seemed to me that Gradle was just a pretty redo of Apache Ant but written in groovy and I started wondering why I was wasting my time on that. 

My advice for those who get the same initial feeling is: carry on reading, it's going to get good really soon.

After reading the quick-start chapter of the Gradle documentation I was able to see the power of this tool but still I had the taste that it was something equals to Ant but prettier and empowered by the fact that the builds are scripted in Groovy. The breakthrough came to me when I started reading about the so called "plugins", these plugins allow a full set of build conventions (like maven plugins) but are extremely simple to configure (unlike maven plugins).

After a little more than two hours of reading, I already had a couple ideas on how to use Gradle for building my apps, so I started migrating a simple tool I have for my day-to-day work. I'd need to say that the learning curve is very smooth.

The project I migrated

To start playing, I took one desktop-app I created to help my day-to-day work, this is just a simple Java based app, with Swing UI but it has an embedded instance of Mule ESB. This app was distributed as a zip file that anyone could execute with two clicks. The following is the pom.xml file I had to build and distribute the app.


I used an archetype that allowed me to easily get the executable file with its dependencies for running, also I had configured the project so it creates a zip file that I can distribute without much effort.

In order to start migrating the app, first I needed to create the Gradle build file, this is a groovy script called "build.gradle", this file is our new "pom.xml".

This is how the final file looks:

The first line of the script applies the java plugin to the project, this imports a predefined build configuration that applies to common java projects.

My project directory structure already had the "/src/main/java", "/src/main/resources", etc that typical maven projects have, I am happy with that structure and I simply didn't wish to change it, fortunately the creators of the java plugin liked these conventions as well and made them to be their standard.

The second line of the script applies the "application" plugin, this is a fantastic plugin that helps you distribute standalone java apps.

Next, I define the naming properties of my project, this is the same concept of the coordinates we need to define for each maven project, the main difference is that these are optional. The name or the artifact will be taken from the name of the folder where the project is contained.

Then, I defined as extended properties the versions of each of my dependencies, my first attempt was to not use the 'ext.' object but Gradle printed a warning when building saying that this is deprecated, It was not obvious to me how to get this done properly, so I took a sneak peak on the spring framework build script to get some inspiration.

After that, I've defined the libraries my project depends on. Gradle provides a more concise syntax for defining this as well but I sticked with the little verbosity that I'm used to because of my maven background.

I configured the main class as a project property as well, this is just required for the application plugin to know what is the entry point of the app.

Finally, I've configured my repos. Since Gradle can use maven repos (but it is not maven) I need to specify that I want the maven central repo to be included, as well as my local repo (.m2/repository), and a couple of other repos I normally configure.

That is all for the migration of my build, let's now take a look at how to use it!

Building and Distributing

To build the project I can simply run:

$ gradle build

The 'build' word is just one of the tasks the java plugin for Gradle has. We have many options i.e. clean, test, etc, just like we would expect from Maven out of the box. For a list of tasks we can run, please take a look at:


Also I can use tasks from the application plugin to run my app:

$ gradle run

And this runs the app from the defined main class. This application plugin has also some very interesting options for me to distribute this app, for example I could create a distribution zip file, tar file, and even os-specific startup scripts, for more information on what you can do with this plugin, just take a look at:


Conclusions

This configuration is just scratching the surface of what you can do with this very powerful build system and also since this is just my first ride, there should be things that I could have done better, for example maybe there is a way to define the default set of repositories for each build.

My overall feeling with this build system is that the configuration is more concise, and making complex configurations that would normally take creating Mojos and a lot of reading, can be simply done with a small amount of groovy.

Even though I din't get the exact same result in my distribution, I like what I had out of the box. My previous distribution was based as well on accepting what I got from an archetype, so in this case, I'd need to say that what comes out of the box is good enough.

What I didn't like is that maven does not regard itself as a mere build tool but it is aimed to standardize projects, I've got the feeling that this idea has been lost on Gradle.

Gradle has surprised me with its simplicity and yet it looks like you can tackle simple and complex things in the same way, this is, of course, thanks to the pre-built plugins, that are, I believe, what makes the difference for the adoption of this tool.

Saturday, May 18, 2013

How to build a cloud connector for Mule ESB

I'm working on a particular project which uses Mule ESB as a central piece, for adding a new feature to my project I need to consume Google's custom search API so for making it beautiful I'm going to create a connector using Mule's DevKit and showing step by step the process of building a connector that consumes a REST API.

First, I create a DevKit module from the archetype:

mvn archetype:generate -DarchetypeGroupId=org.mule.tools.devkit -DarchetypeArtifactId=mule-devkit-archetype-generic -DarchetypeVersion=3.4.0 -DarchetypeRepository=http://repository.mulesoft.org/releases/ -DgroupId=com.mycompany -DartifactId=mule-module-google-custom-search -Dversion=1.0.0-SNAPSHOT -DmuleVersion=3.4.0 -DmuleModuleName=GoogleSearch -Dpackage=com.mulesoft.module.googlesearch -DarchetypeRepository=http://repository.mulesoft.org/releases

Since I'm building a cloud connector for google's custom search API it is handy to have it's reference at hand:

https://developers.google.com/custom-search/v1/cse/list 

You may also want to create a custom search engine:

http://www.google.com/cse/create/new

Lastly: here is the link for the source code of the project:

https://github.com/juancavallotti/mule-module-google-custom-search

Now let's the coding begin! First of all I want to clean up the sample module, pretty much removing everything except the class and it's annotations. I have picked to be a module (instead of a proper connector) because it's a fair simple functionality which does not require work for setting up a connection. The class looks like this:

1
2
3
4
5
6
7
8
9
/**
 * Google custom search Module.
 *
 * @author Juan Alberto López Cavallotti.
 */
@Module(name="google-search", schemaVersion="1.0.0-SNAPSHOT")
public class GoogleSearchModule {

}

So first we will add the required configuration parameters as stated at the documentation, these parameters are the API Key, and the custom search engine ID or it's url (one of both are required). The search query is also required but we'll save it for passing it as a parameter to the only operation this connector will have. I will give nice names to these parameters instead of the really short ones they currently have, this way is more self-documented.


 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
@Module(name="google-search", schemaVersion="1.0.0-SNAPSHOT")
public class GoogleSearchModule {

    @Configurable
    private String apiKey;

    @Configurable
    @Optional @Default("")
    private String searchEngineId;

    @Configurable
    @Optional @Default("")
    private String searchEngineUrl;

    //getters - setters
}


DevKit demands us to write javadoc for each element on the class so it is able to generate the connector's documentation properly. I won't show this documentation on this post unless I have something to say about it, having said that, you might want to take a look at the final version of this module in order to get more insight on its development.

Next, I want to create the one and only operation as a method of this module definition, this method has a lot of parameters, most of all with default values. For me this is pretty ugly and DevKit allows me to do better so I will do, I will pick the most important parameters for direct setting and the others would be gathered through a POJO. The return value I will keep it as the JSON String the service returns (for the sake of simplicity) but kind of more beautiful would be to create an Object Structure and take advantage that Mule has bundled the Jackson Library.


 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
/**
 * Perform a Google custom search.
 *
 * {@sample.xml ../../../doc/GoogleSearchModule-connector.xml.sample google-search:search}
 *
 * @param query The search query to send to google search.
 * @param siteSearch The site where to search.
 * @param searchType The type of the search to be performed.
 * @param searchConfiguration Configuration for this google search.
 *
 * @return The JSON result as returned by the google custom search API.
 */
@Processor
public String search(String query, @Optional @Default("") String siteSearch, 
                     @Optional SearchType searchType, @Optional SearchConfiguration searchConfiguration) {
    return null;
}


You need to consider the following:

  • The method must be annotated with one of the annotations provided by devkit to generate different types of message processors. (Each type has its own signature requirements).
  • Every operation should be documented properly.
  • You need to create a sample usage of the operation on the sample file, (which luckily it gets created by the archetype).
  • You need to document EVERY parameter if you wish the build to succeed.


<!-- BEGIN_INCLUDE(google-search:search) -->
<google-search:search query="#[header:inbound:query]" />
<!-- END_INCLUDE(google-search:search) -->

Now, the sample XML looks like the following:


I want to perform an initial configuration and validation when the module starts just to make sure we're ready to go when making a search so I create a method to take advantage of the configuration element lifecycle:

 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
private HashMap<String, String> connectorConfigs;
 
/**
 * Perform module initialization.
 */
@Start
public void initializeConfiguration() {
    connectorConfigs = new HashMap<String, String>();
 
    connectorConfigs.put("key", apiKey);

    if (StringUtils.isBlank(searchEngineId) && StringUtils.isBlank(searchEngineUrl)) {
        throw new IllegalArgumentException("You must configure either searchEngineId or searchEngineUrl");
    }
 
    if (StringUtils.isNotBlank(searchEngineId) && StringUtils.isNotBlank(searchEngineUrl)) {
        throw new IllegalArgumentException("You must configure a reference to the custom search engine.");
    }
 
    addIfNotBlank(connectorConfigs, "cx" , searchEngineId);
    addIfNotBlank(connectorConfigs, "cref", searchEngineUrl);
}


This basically creates a map that will be the base parameters for every request. Every request should have at least a reference to the API key (which is the way google charges us for our searches) and the reference to our custom search engine (which we need to create manually in order to use the API).  


Next, let's dig into the actual implementation. I will want to access the MuleEvent for this message processor so, I will modify slightly the signature of the method. What this implementation does is: create a map with the parameters to send to the API, then convert these maps into the API url and finally dispatch it through Mule's HTTPS connector. This is very convenient since it allows the configuration of the HTTPS connector parameters even though there is still room for improvement!! I could have made the http connector to use configurable but I won't just to keep it simple. The search method now looks like this:


 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
@Processor
@Inject
@Mime("application/json")
public String search(MuleEvent event, String query, @Optional @Default("") String siteSearch,
                     @Optional @Default("WEB_SEARCH") SearchType searchType, @Optional SearchConfiguration searchConfiguration) {
 
    MuleContext context = event.getMuleContext();
 
    MuleMessage message = event.getMessage();
 
    HashMap<String, String> searchParams = buildSearchParams(query, siteSearch, searchType, searchConfiguration);
 
    String apiUrl = buildSearchUrl(searchParams);
 
    try {
        OutboundEndpoint endpoint = context.getEndpointFactory().getOutboundEndpoint(apiUrl);
 
        //configure the message.
        message.setOutboundProperty("http.method", "GET");
 
        MuleEvent responseEvent = endpoint.process(event);
        //return the payload.
        return responseEvent.getMessage().getPayload(String.class);
    } catch (MuleException e) {
        logger.error("Error while querying the google custom search API", e);
    }
    return null;
}

This is pretty straightforward. I won't get into the implementation of the auxiliary methods because it is just boilerplate. I want to highlight the @Inject annotation I used, this is used to get the actual MuleEvent (and distinguish this parameter from what the user needs to provide) and also the @Mime annotation which will generate the appropriate message header.

Now we just want to create the MuleStudio update site so we can install and try this module:

mvn clean package -Ddevkit.studio.package.skip=false

We can import this through update site and use it! There are furhter configurations I can (and probably will) make to this connector, DevKit has annotations for customizing the studio dialogs and much more!!

Here is a sample project which uses the recently created connector:


<mule xmlns:http="http://www.mulesoft.org/schema/mule/http" xmlns:google-search="http://www.mulesoft.org/schema/mule/google-search" xmlns="http://www.mulesoft.org/schema/mule/core" xmlns:doc="http://www.mulesoft.org/schema/mule/documentation" xmlns:spring="http://www.springframework.org/schema/beans" version="EE-3.4.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans-current.xsd
http://www.mulesoft.org/schema/mule/core http://www.mulesoft.org/schema/mule/core/current/mule.xsd
http://www.mulesoft.org/schema/mule/http http://www.mulesoft.org/schema/mule/http/current/mule-http.xsd
http://www.mulesoft.org/schema/mule/google-search http://www.mulesoft.org/schema/mule/google-search/1.0.0-SNAPSHOT/mule-google-search.xsd">
    
    <google-search:config name="Google_Search" apiKey="<api key>" searchEngineId="<engine id>" doc:name="Google Search"/>
    
    <flow name="mule-configFlow1" doc:name="mule-configFlow1">
        <http:inbound-endpoint exchange-pattern="request-response" host="localhost" port="8081" doc:name="HTTP"/>
        <google-search:search config-ref="Google_Search" query="http connector" doc:name="Google Search" />
        <logger level="ERROR" message="Payload is: #[payload]" doc:name="Logger"/>
        <logger level="ERROR" doc:name="Logger"/>
    </flow>
</mule>

Please continue reading the  DevKit cookbook for much more info:

http://www.mulesoft.org/documentation/display/current/Cloud+Connector+Devkit+Cookbook

Tuesday, May 14, 2013

How To Unit-Test an Annotation Processor

The Issue

I have been developing lately an annotation processor and found that unit-testing it is not as trivial as it might sound.

Some would say "You just need to mock all of the java.lang.model.* packages and that's it!" Unfortunately mocking these elements is not as easy as it might appear and I don't really find a reason why to do this other than speeding up the test suite, this alternative has to be taken real seriously and prioritize the test time / development effort.

The solution

The path I went through is invoking the Java compiler within my unit tests. Doing this is kind of straightforward but some considerations must be taken.

  • In order for the tests to be repeatable, please make sure your working directory is invariant, maven does a good job at this.
  • It's easier if your annotation processor can be auto-discovered. This is place the appropriate "javax.annotation.processing.Processor" file on META-INF/services/
  • Make sure you delete the junk files after you have tested. Since we're going to compile classes some .class files may appear, it is not mandatory to delete them but they would get mixed with the source code which is not nice at all.
Now that we've taken care of the errands, I present you a generic annotation processing test case which you can use for your unit tests.

Please note that this is not the only (or strictly the best) way of doing this but is a way and I like it so, here is the code:


First, we have a simple interface which we will implement to build our test cases, implementations return the list of files to compile and then might verify if the compilation has failed of there were some compilation messages.

Next, we have a really simple sample implementation of a smoke test which verifies that no "Critical Warnings" or "Compiler Errors" have been issued from a valid configuration.

Finally we have the test class. For this I make use of the parameterized test runner that JUnit 4 provides and the parameters are exactly the different implementations of our simple interface.

Please note that in order to be completely generic, this unit test must obtain its parameters from configuration nevertheless I made it like this for the sake of simplicity and just keeping note of the room for improvement.

After this it is just boilerplate code, get the compiler, configure the file manager, compiling the relevant files, invoking the test and finally cleaning up after ourselves.

Please feel free to modify or upgrade this test case and I hope you find it as useful as it is to me. 

Saturday, December 29, 2012

Netbeans-Like Distribution with Maven

When it comes to creating standalone Java applications, out of the box maven projects are not easy to distribute, they don't have configured some default main class (or some convention), dependencies are not specified on the manifest and also dependency jars are not packaged even near the final jar file.

On the other hand, if you have used Netbeans IDE to create standalone Java apps, you can notice that upon any build, the default Netbeans ant build script places a "dist" folder inside your project with the following structure:

This folder is the distribution of your app and you may simply run it with the java -jar command line.

Even though Maven projects have a lot of advantages, I personally miss how handy it is this structure for distribution; so I managed to make this happen with maven and it's assembly plugin.

Building the Distribution Structure

In order to create the desired distribution, I started with maven's jar-with-dependencies predefined assembly and customized it to look like the following:

What this does is the following:

  • It compresses the whole distribution into a nice zip file inside the target directory.
  • The first dependency set is there to copy the application jar on the root of the distribution, I added the none scope to make sure that no other dependencies are copied there.
  • The second dependency set is to copy all dependencies and transitive dependencies into the lib folder.
Now this takes care of the packaging but there is still some work to do, so we need to edit our project's pom.xml file and add the following configurations:

First of all, I've changed the final name of the archive to be short and sweet. Next, I've configured the assembly plugin to point to the right configuration file. Finally I've configured the jar plugin to set in the MANIFEST.MF file the main class and the jars that should be included on the classpath. Please note that you should alter the mainClass configuration to match you main class.

After this, we can create our distribution by simply running:
$ mvn clean package assembly:single

You should find a zip file called like your artifact's ID-dist.zip, which you can nicely share and it's easily run.

Sunday, October 7, 2012

Enterprise Integration with Mule ESB

Why Enterprise Integration?

Beginning on the 90's, having a computer information system is a must for any company; even small drugstores have their own information system; also, starting from the 2000's, having a website is a must for most companies. Nowadays there are lots of online businesses and companies who own a huge ecosystem of applications, websites and third party systems.

In this scenario, one thing naturally emerged: information and business processes is fragmented!

Building a completely new application to mitigate this fragmentation is not practical on most cases so, what should a company do?

The answer is quite simple, something there must be on the middle whether people or software and there is where enterprise integration comes into play.

There is on the Java world also a number of enterprise middleware vendors, some are Mule ESB and Apache Camel and today I'll try to demonstrate how to use the first one which is the one I know better.

Mule ESB

Mule is an open source enterprise service bus which aims to be powerful and simple at the same time. It is very configurable and rather complex integrations can be achieved in a matter of hours.

In order to use Mule ESB, the developer has two main options: It can be used as an application container (with deployment based on archives) or embedded inside a java application.

Every Mule ESB application consists of an XML file which combines a number of built-in building blocks to perform a specific integration task, this task has the name of "flow".

Mule also provides some visual tooling, an IDE based on Eclipse, called "Mule Studio" which greatly helps the developer, to create, package and deploy Mule applications, specially it has visual tooling to create interfaces making the learning curve really flat.

A Sample Mule Application 

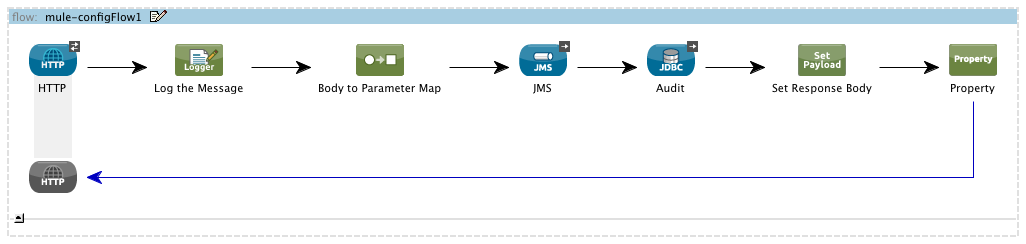
In order to explain further, let's take a look at a simple Mule Application, this application takes requests from http, logs some information, sends information through JMS and inserts records into a database. Any java developer knows that this task may take a couple of hours, but with Mule, this can be done in a matter of minutes. Here is how this application looks in Mule Studio:


Here we have defined a flow (integration), an application may have many flows; the first building block is an HTTP endpoint (called http inbound endpoint) and through the arrows travels a message (actually an instance of MuleMessage). This message contains headers and a payload (also other things such as attachments and other information), with each building block we'll be manipulating or extracting information from it.

I'll not cover in depth the concept of the message but is enough to say that this concept is key for understanding the tool. As an example, imagine a HTTP request, it has headers and a request body, the inbound endpoint will create a mule message with these request headers as the message headers and the request body as the payload. Now, for example, to send the message through JMS, the JMS outbound endpoint would create a JMS message with the Mule message headers as headers and the payload as the JMS payload.

The sample application looks on it's XML form like the following:

The first thing to note is the presence of connectors, these can be seen as a global configuration elements for each transport (in this case JMS and JDBC).

Next we can see the definition of the flow in which we just log the message; set the payload to be a hash map created out of the request query string; send this to an ActiveMQ broker; insert an audit record and finally build a generic JSON response, as you can see a lot is going on for so few configuration lines!

Mule ESB provides out of the box support for several transports such as HTTP, FTP, SMTP, IMAP, SOAP, REST, JMS, JDBC, etc and also ready-to-go clients (called cloud connectors) for popular cloud applications such as Facebook, Twitter, Salesforce and many more.

This completes this short introduction of this tool which is definitely worth looking into when it comes the time for integrating two or more applications.

Monday, August 27, 2012

Apache CXF Working with Spring

These days I have been playing with Apache CXF, which is great open source java-based library for creating both SOAP and REST web services. CXF is a great library, specially if you are using the Spring Framework and despite the outdated and inaccurate documentation, I managed to make it work and here is how to do it.

I have assembled a sample project which is on my GitHub repository.

A Small Introduction


CXF is designed with a very flexible architecture based on interceptors, this architecture allows the developer to make CXF work with different types of front end technologies such as JAX-WS, JAX-RS, CORBA and more!

CXF is also very friendly with the Spring framework so it is (or at least should be) very easy to integrate in this kind of applications.

Working with Maven

CXF artifacts are published on the central maven repository, so first of all, you need to add the dependencies into your project:


<dependency>
    <groupId>org.apache.cxf</groupId>
    <artifactId>cxf-rt-frontend-jaxws</artifactId>
    <version>${cxf.version}</version>
</dependency>
<dependency>
    <groupId>org.apache.cxf</groupId>
    <artifactId>cxf-rt-frontend-jaxrs</artifactId>
    <version>${cxf.version}</version>
</dependency>
<dependency>
    <groupId>org.apache.cxf</groupId>
    <artifactId>cxf-rt-transports-http</artifactId>
    <version>${cxf.version}</version>
</dependency>

At the moment of writing this post CXF latest version is 2.6.2. Also you need to include dependencies for the Spring Framework, please refer to the sample project for these.

Spring Configuration

To start with this little how to, I created a service class with has mixed JAX-WS and JAX-RS annotations. This makes easy to export the same functionality as SOAP and REST web services:


@WebService
@SOAPBinding(parameterStyle = SOAPBinding.ParameterStyle.BARE)
public interface MyWebService {

    @WebMethod
    String doSomeWork(String work);
    
    
    public String beRestful(String name);
    
    
    @WebMethod
    public ArrayList<Customer> findCustomers(CustomerRequest request);
}

And the implementation:


@WebService
public class MyWebServiceImpl implements MyWebService {
    
    @WebMethod
    @Override
    public String doSomeWork(String work) {
        return "Doing some work with this: "+work;
    }
    
    
    @Override
    @GET @Path("/beRestful") @Produces("text/plain") //REST Annotations
    @WebMethod //SOAP Annotations
    public String beRestful(@QueryParam("name") String name) {
        return "Your name is: "+name;
    }
    
    
    @WebMethod
    public ArrayList<Customer> findCustomers(CustomerRequest request) {
        
        
        ArrayList<Customer> ret = new ArrayList<Customer>();
        
        Customer customer = new Customer();
        
        customer.setCustomerName(request.getName());
        customer.setMembershipLevel(request.getMembershipLevel());
        customer.setCustomerSince(new Date());
        
        ret.add(customer);
        
        return ret;
    }
    
}


The Customer and CustomerRequest classes are pretty simple and therefore not shown here, please refer to the sample project for the source code.

These exposes three methods through SOAP and one through REST, CXF has its own XML namespaces for JAX-WS and JAX-RS, the header of the applicationContext.xml file looks like the following:


<beans xmlns="http://www.springframework.org/schema/beans"
       xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
       xmlns:context="http://www.springframework.org/schema/context"
       xmlns:util="http://www.springframework.org/schema/util"
       xmlns:p="http://www.springframework.org/schema/p"
       xmlns:jaxws="http://cxf.apache.org/jaxws"
       xmlns:jaxrs="http://cxf.apache.org/jaxrs"
       xsi:schemaLocation="http://www.springframework.org/schema/beans http://www.springframework.org/schema/beans/spring-beans-3.1.xsd
          http://www.springframework.org/schema/context http://www.springframework.org/schema/context/spring-context-2.5.xsd/spring-spring-context-3.1.xsd-3.1.2.RELEASE.xsd
          http://www.springframework.org/schema/util http://www.springframework.org/schema/util/spring-util-3.1.xsd
          http://cxf.apache.org/jaxws http://cxf.apache.org/schemas/jaxws.xsd
          http://cxf.apache.org/jaxrs http://cxf.apache.org/schemas/jaxrs.xsd
">


CXF also has its own configuration files included inside the JAR files, even though these files look empty, the documentation suggests to include them so here are the lines for it:


    <!-- import cxf webservices -->
    <import resource="classpath:META-INF/cxf/cxf.xml" />
    <import resource="classpath:META-INF/cxf/cxf-servlet.xml" />

Finally, we need to declare the bean we just created as a Spring Bean and reference it in a SOAP and a REST endpoint:


    <jaxws:endpoint 
        id="mywebservice" 
        implementor="#webserviceImpl" 
        address="/myws" />
    
    
    <jaxrs:server id="myrestservice" address="/rest">
        <jaxrs:serviceBeans>
            <ref bean="webserviceImpl" />
        </jaxrs:serviceBeans>
    </jaxrs:server>
    
    <bean id="webserviceImpl" class="com.juancavallotti.cxfdemo.MyWebServiceImpl" /> 

The last ingredient is configuring the CXF servlet in our web.xml file.

Configuration of web.xml

The configuration of this file is pretty standard, first I have declared the CXF servlet and map it to the /ws/* URL pattern, and then I just declared the standard listeners for the Spring Framework to work on a web environment.


    <!-- the cxf servlet -->
    <servlet>
        <servlet-name>cxfservlet</servlet-name>
        <servlet-class>org.apache.cxf.transport.servlet.CXFServlet</servlet-class>
    </servlet>
    <servlet-mapping>
        <servlet-name>cxfservlet</servlet-name>
        <url-pattern>/ws/*</url-pattern>
    </servlet-mapping>
    
    <!-- spring context and request listeners -->
    <listener>
        <listener-class>org.springframework.web.context.ContextLoaderListener</listener-class>
    </listener>
    <listener>
        <listener-class>org.springframework.web.context.request.RequestContextListener</listener-class>
    </listener>

Running the example


After following these steps we are ready to run the example application, if you have forked or cloned the sample application just run: $ mvn tomcat:run command line and after the startup, point the browser to: http://localhost:8080/CxfDemo/ws, you should see a very simple webpage that informs the webservices running on the CXF servlet and links to the WSDL and the WADL:


Conclusions

CXF is a very powerful and complete framework for exposing services as web services, I think it is the natural choice if you want to enable web services in your spring application. Be aware that you will find outdated documentation and be sure to read the documents about the architecture before planning to reverse-engineer the framework or else you'll find the task rather frustrating.


Sunday, July 15, 2012

Concurrency Tests with JUnit

Sometimes in the life of a programmer, a concurrency test is needed to check if a given framework function doesn't break the data when used simultaneously by different threads.

JUnit provides some sense of AOP by using the @Rule annotation which allows us to modify how a given test runs. I was trying to create these kind of tests for my DTO framework (jDTO Binder) and inspired by this blog post, I created a test rule that allows the programmer to specify the number of threads to run a given test case and collect some little statistics about the running time of the test.

First of all I created an implementation of TestRule.


The previous gist may be used by anyone who would like to create concurrency tests and dont care that much about the execution exceptions but rather the overall results of the tests.

The code does the following:

  1. Create a ThreadPoolExecutor with the size of the tests, you may use other executor implementation if you wish so.
  2. Create a CountdownLatch to make sure all the tests start almost at the same time.
  3. Create a CountdownLatch to block the test thread until all tests finish.
  4. Add all the required tasks to the executor, which will wait until all all have been scheduled.
  5. If some test fails, then a flag will be set to true.
  6. Log the execution time.
  7. Fail the test if some of the threads had an exception.
So at this point we're ready to use the rule on a simple concurrency test:


And as simple as that we have a concurrency test with some statistics on the running time.

Tuesday, June 19, 2012

Websockets on Tomcat 7

Recently I discovered Tomcat 7 supports websockets, I looked at the support and found it quite easy to use.

I have created a very simple websocket servlet that echoes the input from the user, first of all you need to create a class that extends from WebSocketServlet, then, for every subprotocol you want to handle, you need to create a subclass of the abstract MessageInbound. There you may choose to answer to text or binary messages, here is the source:


Now we can connect to the websocket from our javascript client code:


And as simple as that we have our web sockets working for our java application deployed on Tomcat 7.

Sunday, May 20, 2012

Wicket 1.5 + Spring Framework + Hibernate + jDTO Binder Sample Application

In this post I'll go through a sample project I've created to demonstrate jDTO Binder in action with some of the most popular frameworks on the Java world. The sample project is publicly available on GitHub.

To get the project running without too much fuss, then just checkout the project, open it on netbeans 7.1.2 and hit run :)

If you're on linux or mac os X then you can do something like this:

$ git clone git://github.com/jDTOBinder/jdto-sample-projects.git
$ cd jdto-sample-projects/jdto-wicket-demo/
$ mvn clean tomcat:run

After that you may point your browser to http://localhost:8080/jdto-wicket-demo/ and that's it, you should see something like this:


The CSS3 Highlights:

The styling is pretty standard styling what can be kind of uncommon is the menu box which is rotated and it has a little shadow, also some google web fonts are being used, let's go with the easiest first, the shadow:

box-shadow: 6px 6px 5px #888;

The parameters mean in order, the horizontal distance, the vertical distance the blur distance and the shadow color.

Also you can see that the box is kind of rotated let's say 8 degrees to the left? Normally that would have been defined by using the transform property, but it seems that is still not that supported in all browsers, so I have added three rules to support webkit, mozilla and internet explorer 9:

-webkit-transform:rotate(-8deg);
-moz-transform:rotate(-8deg);
-ms-transform: rotate(-8deg);

Finally, to include some web fonts, some import statements must be added:

/* import the google web font  */
@import url(http://fonts.googleapis.com/css?family=Averia+Libre:700);
@import url(http://fonts.googleapis.com/css?family=Oxygen);

That enabled me to use the "Averia Libre" and "Oxygen" fonts on my styles.

The Wicket Highlights

Apache Wicket is a really nice web framework that you can use to build everything in Java, from websites to web applications, there are some things that may be uncommon for some developers, I've used the wicket:link tag to include css resources packaged on the classpath:

<head>
    <title>jDTO Binder Pizza Orders!</title>
    <wicket:link>
        <link rel="stylesheet" type="text/css" href="jdtopizzas.css" />
    </wicket:link>
</head>

Normally one would have had that css resource included on the java code but this wicket magic makes it more intuitive and consistent.

Another use of the tag is to link between pages, as I show in the following example:

<p>Take a look at the <wicket:link><a href="ViewOrdersPage.html">orders you have already created</a></wicket:link>.</p>

In this case, I have a ViewOrdersPage.java file and by creating the link this way, wicket takes care of pointing the href to the right place without adding extra Java code.

DTOs as the Wicket Models

Wicket extensively uses "intermediate" objects to act as the model of it components this is where DTOs come in handy, since you can modify the data they carry without affecting the data on the database, they are perfect for using them as the components model. The following code shows how you bind a wicket form with the "form" that takes the service to create a new pizza order:

PizzaOrderForm form = new PizzaOrderForm();
form.setPizzas(new ArrayList<PizzaDTO>());

//create the order form.
orderForm = new Form<PizzaOrderForm>(
        "orderForm",
        new CompoundPropertyModel<PizzaOrderForm>(form));

//for the case you want to add pizzas and you have already filled the form elements.
//this is only necessary because I left out the menu list from the form.
orderForm.add(new TextField("customerName").add(new BlurAjaxFormSubmitBehavior()));
orderForm.add(new TextField("customerPhone").add(new BlurAjaxFormSubmitBehavior()));
orderForm.add(new TextField("customerAddress").add(new BlurAjaxFormSubmitBehavior()));

With the use of CompoundPropertyModel things are really easy. I've added a behavior that submits the form data every time the field losses focus, this prevents unwanted data erasing on the client side. (Also I could have designed my page a little better hehe).

Spring and Hibernate Highlights

As this is a sample application but is intended to show real-life stuff, it uses spring framework and hibernate, but if you had to install and configure a database server to test the application, you probably wouldn't test it, so here is how I've used the H2 embedded database engine to use just your computers memory a little bit more:

<bean id="dataSource" class="org.apache.commons.dbcp.BasicDataSource" destroy-method="close">
    <property name="driverClassName" value="org.h2.Driver"/>
    <property name="url" value="jdbc:h2:mem:pizza"/>
</bean>

As you can see, the database connection pool has the url "jdbc:h2:mem:pizza" and that is all what it takes to tell H2 that you don't want to persist anything.

Finally, I've used a singleton bean to load the sample data when the application starts, this bean loads the list of available products.

<!-- initial data loader bean -->
<bean id="initialDataLoader" class="org.jdto.demo.InitialDataLoader" />

class InitialDataLoader {
    
    private static final Logger logger = LoggerFactory.getLogger(InitialDataLoader.class);
    
    @Autowired
    private HibernateTemplate template;
    
    @PostConstruct
    @Transactional(propagation= Propagation.REQUIRES_NEW)
    private void init() {
        createPizzas();
    }

    private void createPizzas() {
        logger.info("Creating initial set of pizzas!");
        
        Pizza pepperoni = new Pizza("Pepperoni Pizza", 4, 8.50);
        Pizza mozzarella = new Pizza("Mozzarella Pizza", 3, 7.50);
        Pizza special = new Pizza("Special Ham Pizza", 5, 10.0);
        Pizza onion = new Pizza("Onion Pizza", 4, 9.0);
        Pizza anchovy = new Pizza("Anchovy Pizza", 2, 7.95);
        
        template.save(pepperoni);
        template.save(mozzarella);
        template.save(special);
        template.save(onion);
        template.save(anchovy);
    }
}

One of the beauties of Spring is that you can use package-scoped classes as beans so you don't expose them to the team developers (and they don't feel tempted to use them).

Since this bean will be executed on startup time we will need a brand new transaction, so I've set the propagation attribute to "requires new".

jDTO Binder Highlights

In this application, jDTO Binder takes care of copying data between domain objects and DTO objects, how it's being used is described on the project's README file.


That would be all for now, please feel free to make comments on the post and I hope you find it useful for starting a new project with this great technologies.